Latest Sessions
View All Sessions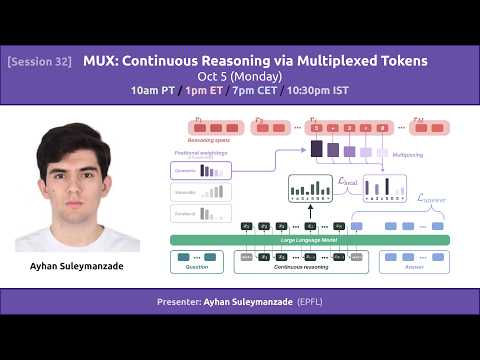
S32 | MUX: Continuous Reasoning via Multiplexed Tokens
Ayhan Suleymanzade presents MUX, which distills discrete chains of thought into continuous multiplexed tokens, where each latent token represents a weighted linear superposition of a span of reasoning subwords that is lossless by construction and fully recoverable. The authors prove that simple position-dependent weightings such as geometric decay support lossless multiplexing, which prevents the shortcut behaviors caused by latent collapse, and they show multiplexed reasoning can explore in parallel on search problems. Across 32 evaluation settings and four language models, MUX beats strong latent reasoning baselines.
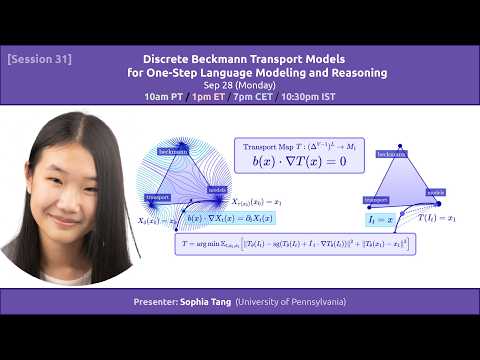
S31 | Discrete Beckmann Transport Models for One-Step Language Modeling and Reasoning
Sophia Tang presents Discrete Beckmann Transport Models, which reach one- and few-step generation in discrete flow models without distilling a pretrained teacher. DBTM builds on a time-independent flow whose autonomous transport map provably carries any point to a fixed point on the vertices of the simplex in a single step, a property characterized by a conservation equation whose residual is minimized directly from data. Generation then reduces to iterating one map until it reaches a fixed point, improving quality and accuracy over discrete diffusion and continuous flow baselines.
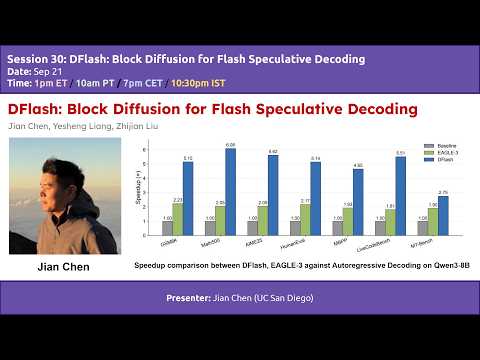
S30 | DFlash: Block Diffusion for Flash Speculative Decoding
Jian Chen presents DFlash, a speculative decoding framework that replaces autoregressive drafting with a lightweight block diffusion model, so all draft tokens come out of a single forward pass. Conditioning the draft model on context features extracted from the target model keeps draft quality and acceptance rates high. DFlash reaches over 6x lossless acceleration across a range of models and tasks, up to 2.5x higher speedup than EAGLE-3.
Featured Videos
View All Videos
How did diffusion LLMs get so fast?
Techniques for accelerating diffusion LLMs, from self-distillation and curriculum learning to KV caching and block diffusion
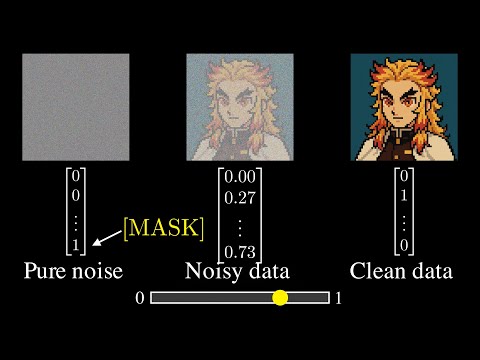
But How Do Diffusion Language Models Actually Work?
Jia-Bin Huang explores several ideas for applying diffusion models to language modeling
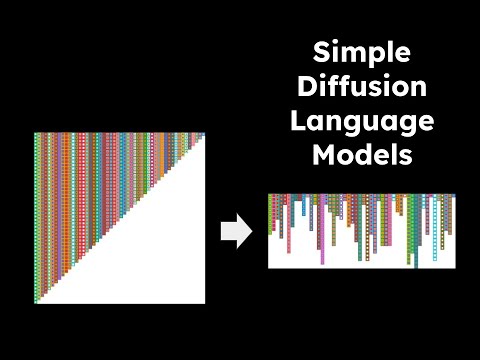
Simple Diffusion Language Models
Quick introduction to Masked Diffusion Language Models (MDLM) by Alexander Rush
About the Reading Group
Diffusion LLMs are faster, more controllable successors to traditional LLMs and are rapidly gaining adoption. This reading group builds a community for exchanging and debating emerging ideas in this space. While our primary focus is discrete diffusion models for language, we also welcome work on other modalities and applications, such as molecular design, drug discovery, and beyond.
Meet the Organizers
Subham Sahoo
Holds a Ph.D. from Cornell Tech, where he specialized in Diffusion Language Models. He has made foundational contributions to the field, with his work deployed at scale by Google, NVIDIA, and ByteDance across language generation and drug discovery.
Justin Deschenaux
PhD student in Machine Learning at EPFL, advised by Prof. Caglar Gulcehre. Previously interned at Apple MLR. His research interests include diffusion language models, fast generative models, and generalization.